FDR, Match-Between-Runs, and Immunopeptidomics: A Plain-Language Guide
What is FDR in proteomics?
The false discovery rate (FDR) is the estimated fraction of reported identifications that are incorrect. In proteomics, controlling FDR is how we ensure that peptide and protein identifications can be trusted.
When a search engine matches a fragmentation spectrum to a peptide sequence, it assigns a score to that match. Some matches are correct — the spectrum really came from that peptide. Others are incorrect — the peptide sequence happens to fit well by chance, or another peptide matches even better. The FDR is the proportion of reported matches that fall into the incorrect category.
By convention, proteomics results are reported at 1% FDR — meaning that at most 1 in 100 reported identifications is expected to be wrong. This threshold applies at multiple levels: peptide-spectrum match (PSM) level, peptide level, and protein level. Each requires its own FDR control.
Why FDR matters for comparing tools
A search engine that reports 20% more peptide identifications is only doing something meaningful if those extra identifications are real — if the FDR is still accurately controlled at 1%. A tool that loosens its FDR threshold, or uses a procedure that underestimates the true error rate, can appear to find more peptides while actually reporting more errors. This is why FDR methodology is one of the most important — and most scrutinized — aspects of proteomics software.
The key question: When a tool says "1% FDR," is the observed error rate actually no worse than 1%? The only way to verify this independently is with an entrapment experiment — searching against a database containing a foreign proteome that cannot legitimately be present, and counting how many identifications fall in that foreign set.
The target-decoy approach
The target-decoy approach is the standard method for estimating FDR in proteomics. It works by searching against a combined database of real (target) and fake (decoy) sequences, then using the decoy hit rate to estimate the error rate among target hits.
Decoy sequences are typically generated by reversing each protein sequence in the database. Because reversed sequences cannot be correct matches, any decoy sequence that scores above a given threshold is, by definition, a false positive — a real sequence that happened to score well by chance. Counting decoys above the threshold and dividing by targets above the threshold gives the FDR estimate.
When decoys are used for two jobs at once
Most modern search tools also use a second-stage classifier — Percolator, PeptideProphet — to rescore identifications using dozens of features. To train this classifier, they use decoy sequences as negative examples. This means the same decoys are doing two jobs: training the classifier and measuring the FDR.
This creates a subtle but real problem. A classifier trained to recognize decoys can learn the specific patterns of reversed sequences rather than genuine incorrectness. When those same decoys are then used to estimate the FDR, the estimate is no longer fully independent — and the reported error rate can be lower than the true rate. This failure mode has been studied in the FDR-control literature and is one of the motivations behind the Tesorai Search design.
The Tesorai approach: The Tesorai model is trained entirely on real peptide-spectrum matches — never on decoys. Decoys are reserved exclusively for FDR estimation after scoring, making the error estimate fully independent of the model. An entrapment analysis confirmed that the measured false discovery proportion stays at or below the claimed FDR across thresholds from 0.1% to 10%.
What is match-between-runs (MBR)?
Match-between-runs (MBR) recovers peptides that were identified in some runs of an experiment but not in others. It uses identifications from the other runs to decide where to look in the run with the gap.
How a recovered identification is then checked depends on how the data were acquired. That difference determines how much evidence stands behind each recovered value.
A missing identification is not evidence of absence
Quantitative proteomics produces a table of peptides by samples, and that table usually has gaps. A gap means the search did not report the peptide in that run. On its own, it does not show that the peptide was absent from the sample.
Several things can produce a gap. The peptide may be absent, or below the detection limit. It may also have been present and detectable but never fragmented. In data-dependent acquisition (DDA), the instrument fragments only a handful of the most intense precursors from each survey scan, and which ones make the cut varies from run to run. A peptide identified in most samples can be missed in others by chance.
Treating these gaps as zeros, or as proof of absence, can create false differences between groups. MBR targets the gaps that come from sampling rather than from biology.
How conventional MBR works in DDA
In DDA, an identification normally rests on an MS2 (fragment) spectrum: the instrument isolated the peptide, broke it apart, and the fragment pattern matched the sequence. MBR fills a gap differently:
- Align retention times. Peptides identified in two runs are used to map retention times between them, because elution times drift between injections.
- Predict where the missing peptide should be. A peptide identified in run A but not in run B is given a predicted retention time in run B.
- Look for a matching MS1 feature. The software searches run B's survey (MS1) data near that time for a signal with the expected mass and charge.
- Transfer the identity. If a suitable feature is found, it is quantified and labelled with the peptide identity from run A.
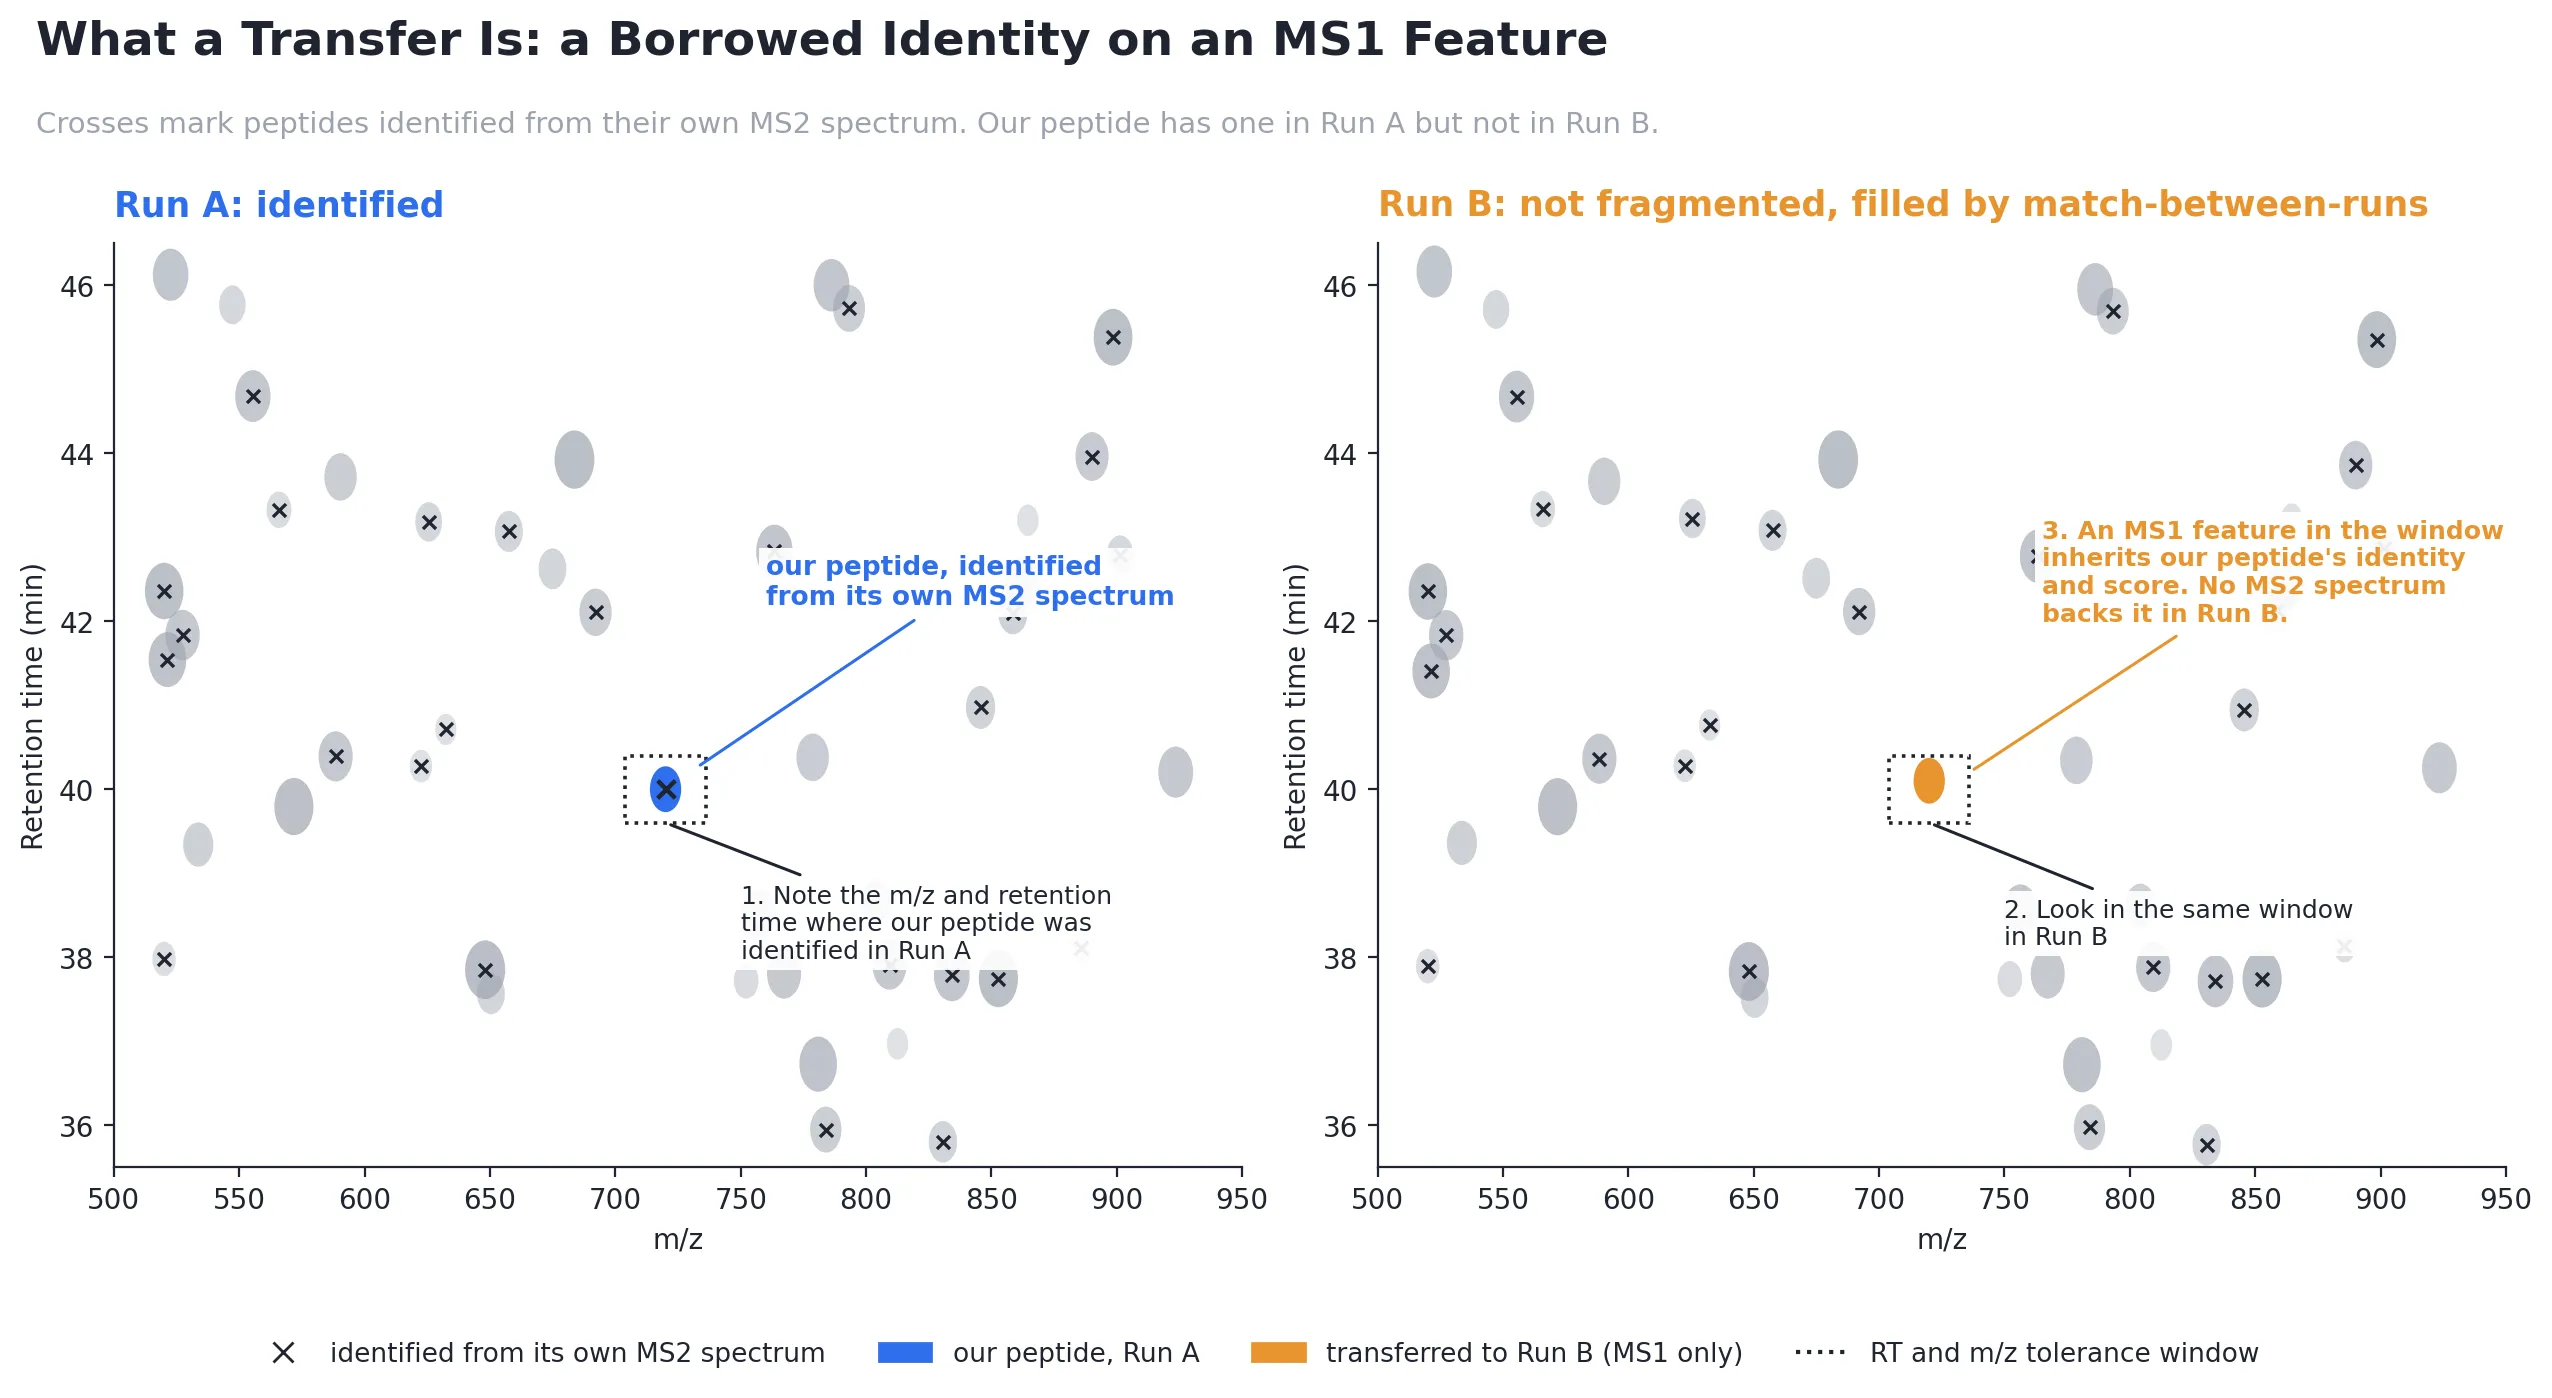
The signal in run B is real, but it is a mass at a retention time. The sequence assignment came from another run. Often run B has no fragment spectrum for the peptide because it was never selected; when one was recorded, it was not good enough to identify the peptide. Either way, the transfer rests on MS1 evidence. With DDA data this is often the best evidence available, but it is a different kind of evidence than a fragment-supported identification.
Why identification FDR does not automatically cover transfers
The false discovery rate a search engine reports is estimated for identifications made from fragment spectra. A transfer is a separate decision: is this MS1 feature in run B the same peptide identified in run A? That decision can be wrong even when the source identification is correct, for example when a different peptide of similar mass elutes near the predicted time. Whether transfers are error-controlled depends on the software and its settings. It cannot be assumed from the reported identification FDR.
A two-proteome experiment by Lim and colleagues measured how often transfers go wrong (J. Proteome Res. 2019). They analyzed 20 samples containing yeast and 20 samples with no yeast, together, with MBR on. Any yeast identification in a yeast-free sample had to be incorrect. Some such errors can arise in any search, from fragment spectra matched to the wrong sequence; the study focused on the errors MBR adds, where a yeast identity was transferred into a yeast-free run.
- MBR increased total identifications by roughly 40%.
- 44% of all identified yeast proteins were transferred into at least one yeast-free sample. The denominator is identified yeast proteins, not transferred identifications.
- Downstream label-free quantification filtering in MaxQuant removed most of these false transferred protein identifications before the final quantitative table.
The lesson is not that MBR is unusable. False transfers were common at the transfer step, most were removed later in that workflow, and the transfer step itself did not report how many accepted matches were wrong.
Transfer-specific error control addresses that last point. IonQuant, for example, estimates the false-transfer rate by modelling the distribution of transfer scores (Yu, Haynes & Nesvizhskii, Mol. Cell. Proteomics 2021). Other approaches propose decoy transfers alongside real ones, or learn from transfers whose correct answer is already known. The shared goal is a measured error rate for transfers, rather than a fixed tolerance window that is assumed to be good enough.
What changes with DIA
In data-independent acquisition (DIA), the instrument does not choose which peptides to fragment. It steps through fixed mass windows and fragments everything in each window, every cycle, for the whole run. The resulting fragment spectra are mixtures of many peptides, so DIA software tests a candidate by extracting the signal for each of its expected fragments over time and checking whether those traces rise and fall together.
This changes what MBR can do. Because acquisition covers the whole scanned mass range, the receiving run contains fragment data at the candidate's mass and expected elution time. Coverage is not the same as evidence: if the peptide is absent, too faint or buried in interference, those data will not support it. Other runs can suggest where to look, and the candidate can then be tested against fragment data from the receiving run itself. If it is scored like every other identification and included in the same FDR calculation with decoys, the recovered identification carries its own evidence and its own error control.
DIA does not make every recovery correct. It makes each recovery checkable against data from the run where it is reported.
Questions to ask about recovered identifications
- Evidence: What supports the identification in the run where it is reported: an MS1 feature only, or fragment evidence from that run?
- Error control: Is the error rate of the transfer step estimated, and how (decoy transfers, a fitted score model, examples with known answers)? Is it controlled separately or within the main FDR?
- Traceability: Are recovered values flagged in the output so you can count, filter or exclude them? Can you open the evidence behind an individual recovered identification?
- Scope of reported gains: When a tool reports more identifications, do the numbers include MBR recoveries?
How Tesorai handles this: Tesorai Search offers MBR as an option for both DDA and DIA; for DDA it is off by default. When it is enabled for DDA, jobs large enough to calibrate estimate their own wrong-transfer rate and set the acceptance cutoff from it, but the evidence in the receiving run is still an MS1 feature. In DIA, each recovered peptide is rescored against fragment data from the receiving run and passes the same FDR calculation as every other identification. MBR-recovered identifications are marked in the output CSV and in the dashboard’s ‘is mbr’ column. The published benchmark gains for Tesorai Search were measured without MBR. See How Tesorai Works: Match-Between-Runs for details, and the technical posts on MBR in DDA and MBR in DIA.
What is immunopeptidomics?
Immunopeptidomics is the mass spectrometry-based study of peptides presented on the surface of cells by MHC (major histocompatibility complex) molecules — the peptides that the immune system uses to survey cellular contents for signs of disease.
Every nucleated cell in the body continuously digests its own proteins and presents fragments of them on its surface via MHC class I molecules. CD8+ T cells patrol these surfaces, and when they recognize a peptide as foreign — from a virus, a mutation, or a cancer-specific alteration — they mount an immune response. The collection of peptides presented by a cell at any given time is called the immunopeptidome.
Characterizing the immunopeptidome by mass spectrometry has become a cornerstone of cancer immunotherapy research. It enables identification of neoepitopes — peptides derived from tumor-specific mutations — that can be targeted by T cells or used to design personalized vaccines. It is also essential for understanding which viral peptides are presented during infection, relevant to vaccine design and antiviral therapy.
Why immunopeptidomics is analytically challenging
Immunopeptidomics is substantially harder than standard proteomics for several reasons. MHC-presented peptides are short (8–11 amino acids for MHC class I; 13–25 for class II) and do not arise from enzymatic digestion — so search engines must use unspecific cleavage, generating a far larger search space. The peptides are also present at very low copy numbers, requiring highly sensitive instruments and analysis software. Finally, the diversity of MHC alleles across individuals means that different patients present different peptide repertoires, requiring careful database construction.
Why identification depth matters especially here: In immunopeptidomics, every additional identified peptide is a potential neoepitope — a target for immunotherapy. A search engine that identifies 20% more peptides from the same raw data is not just a technical improvement; it may reveal therapeutic targets that would otherwise be missed entirely.
Tesorai Search and immunopeptidomics
Tesorai Search supports immunopeptidomics workflows natively, using unspecific enzymatic digestion with configurable peptide length ranges (typically 8–15 amino acids for MHC class I). In benchmarks on published immunopeptidomics datasets — including Bassani-Sternberg et al. and Nowatzky et al. — Tesorai identified 62% and 59% more peptides than MaxQuant, respectively, and outperformed FragPipe, PEAKS, and Proteome Discoverer at 1% FDR.
Putting it together: what to look for in a proteomics pipeline
The three concepts above — FDR control, match-between-runs, and immunopeptidomics-specific challenges — converge on a single practical question: how do you know whether to trust your search results?
A rigorous proteomics pipeline should be able to answer four questions clearly:
- Is the FDR estimate independent? Were decoys used only for error estimation, or also for training the classifier? If the same decoys trained the model and measured the error, the FDR may be optimistic.
- What evidence supports each identification in the run where it is reported? For identifications recovered by match-between-runs, is the evidence an MS1 feature, measured in that run but with its peptide identity transferred from another run? Or is the candidate tested against fragment data from that run? Are recovered values flagged so you can inspect, filter or exclude them?
- Is the error rate of recovered identifications measured? Is it estimated with transfer-specific methods or within the same FDR calculation as other identifications, rather than assumed from the identification FDR?
- Has the FDR been independently verified, and are gains reported separately? Does the tool provide entrapment results showing that the observed error rate matches the claimed rate? Are benchmark gains kept separate from identifications added by match-between-runs?